OpenAI details how it says it is fighting adversarial distillation
OpenAI describes its safeguards against adversarial distillation and says it took enforcement action against multiple campaigns weekly this year.
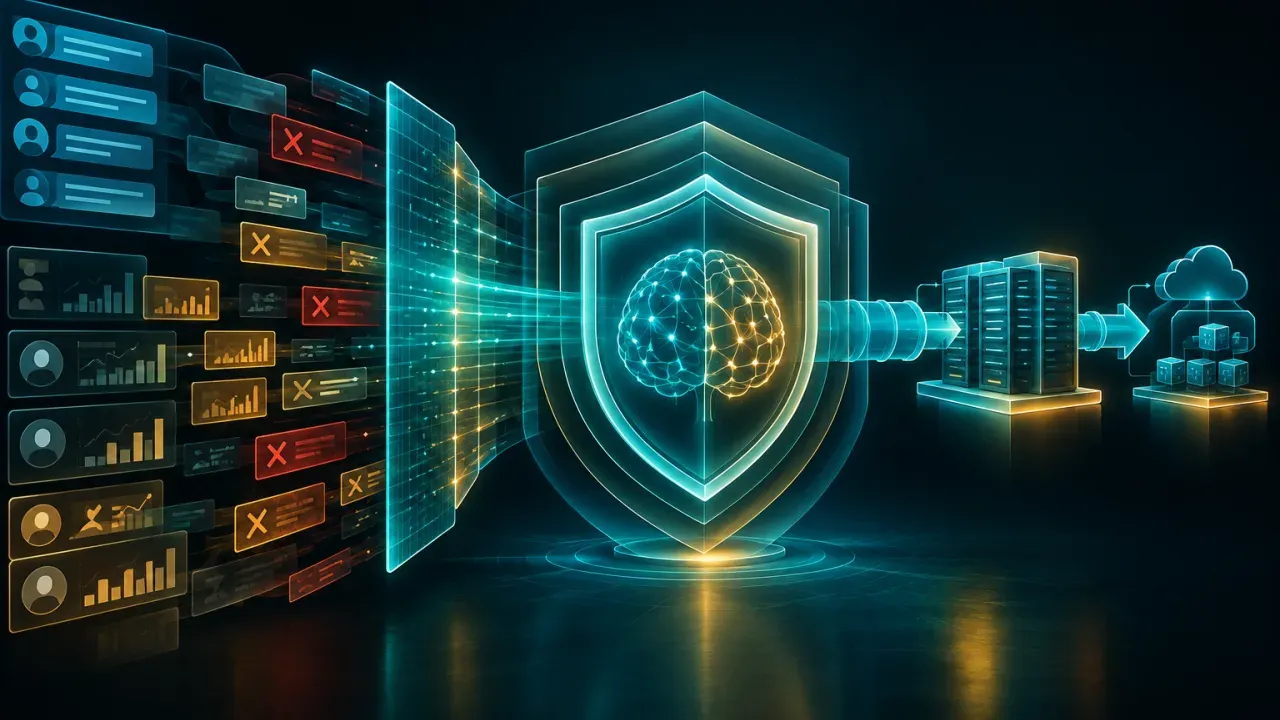
- OpenAI says adversarial distillation can let an actor use a frontier model’s outputs to train a similar model without equivalent safeguards.
- The company says its defences combine per-request safeguards with campaign detection, investigations and automated red-teaming.
- OpenAI says it has seen multiple unauthorised distillation campaigns this year and that weekly enforcement actions have ranged from thousands to tens of thousands of accounts.
- It says it also tracks prevalence of distillation abuse and the time between detection and enforcement to judge whether its response is working.
OpenAI has published a new post on adversarial distillation, laying out how it says it is trying to stop actors from extracting frontier model capabilities and redeploying them without the original safeguards. The company frames the issue as a security problem, not just a policy one: if an attacker can reproduce a model’s useful behaviour from its outputs, they may be able to ship a similar system without the protections the original developer put in place. OpenAI, “Combatting adversarial distillation”
What OpenAI says adversarial distillation looks like
In the post, OpenAI says an actor may use a frontier model’s outputs without authorisation to train another model with similar capabilities, then deploy that model without comparable protections. It gives a cyber example: a distilled model could help carry out attacks that the original model would have refused to assist with, or that its safeguards would have blocked. That matters for teams building with model APIs because the security question is not only what a model will answer directly, but also how easily its behaviour can be copied into a separate system. OpenAI, “Combatting adversarial distillation”
Why it matters
OpenAI’s argument is that the risk extends beyond one product and into the wider ecosystem. A copied model can preserve capability while dropping safety layers, which makes enforcement harder once the extraction has happened. The company also says adversarial distillation can create national security risk if a foreign actor reproduces advanced capabilities from a U.S. model and deploys them without the developer’s protections. OpenAI, “Combatting adversarial distillation”
For developers and security teams, the practical takeaway is that a model provider’s mitigation strategy needs to work at more than one layer. Blocking a single malicious prompt is not enough if the same actor can continue extracting useful outputs across many requests and accounts.
The defence stack OpenAI says it uses
OpenAI says its defences combine safeguards for individual requests with campaign detection and enforcement. It adds that attacks uncovered in investigations become examples for training and testing its safeguards, and that findings from investigations and automated red-teaming help strengthen those controls. OpenAI, “Combatting adversarial distillation”
| Layer | OpenAI’s described approach | What it is trying to stop |
|---|---|---|
| Individual requests | Safeguards on single prompts and responses | Direct extraction through one-off misuse |
| Campaign detection | Patterns in request-level and account-level signals | Coordinated extraction across many requests |
| Enforcement | Action against accounts involved in campaigns | Ongoing abuse at platform level |
OpenAI says it measures effectiveness by tracking the prevalence of distillation abuse and the time between detection and enforcement. Those are useful operational signals because they focus on both how often abuse appears and how quickly the response lands. OpenAI, “Combatting adversarial distillation”
What OpenAI says it has seen so far
The company says it has seen multiple unauthorised adversarial distillation campaigns on its platform this year, and that weekly enforcement actions against those campaigns have ranged from thousands to tens of thousands of accounts, with the rate increasing significantly this past summer. That is the clearest public signal in the post that OpenAI is treating the problem as an active operational issue rather than a theoretical one. OpenAI, “Combatting adversarial distillation”
What is still unknown
OpenAI does not publish the underlying detection rules, the exact account action thresholds, or how much capability was actually extracted in the campaigns it references. It also does not say which safeguards are most effective in isolation. For readers evaluating similar systems, the post is better treated as a description of a defence programme than as a complete benchmark of its success. OpenAI, “Combatting adversarial distillation”
Individual request safeguards
Controls at the prompt-and-response level aimed at blocking direct extraction.
Campaign detection and enforcement
Pattern-based detection across requests and accounts, followed by action against campaigns.
Investigations and automated red-teaming
Findings from investigations and testing are used to strengthen defences.